A green test suite does not tell you whether the AI system solves the task
A caseworker at an unemployment insurance fund asks an AI assistant whether a member is entitled to benefits from 1 March. The answer can be fluent, correctly formatted and wrong. No classic software test will catch it.
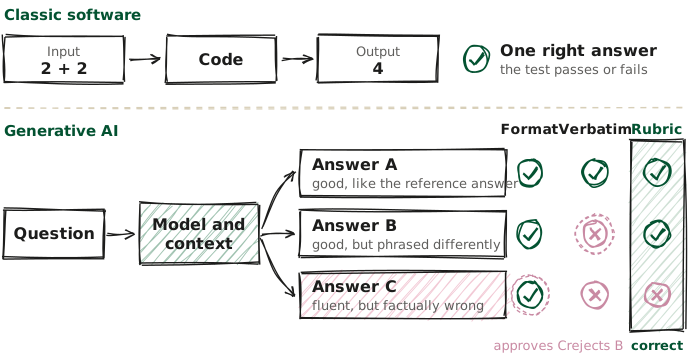
A classic test has one right answer: given a specific input, we expect a specific output, and the test passes or fails. Generative AI has no single right answer. Two different answers can both be good, and a well-phrased answer can be factually wrong. A test that compares word for word with a reference answer discards the good answer that is phrased differently. A format test approves the wrong one.
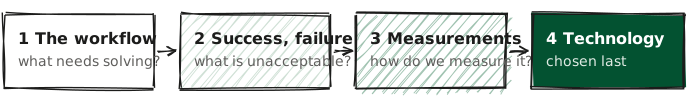
The discipline we use instead we call EvalOps: define what good means, test it systematically, steer development by the results and keep going after go-live. The full method is in our white paper Assuring AI quality takes more than testing. In practice, most of the value lies in five moves.
Success is defined in the workflow
The most important measurement is rarely a generic score such as faithfulness or answer relevance. It depends on the task. For a meeting assistant, it is whether every decision makes it into the minutes, and whether they contain anything that was never said. For an agent that has to book a meeting, it is whether the meeting gets booked. For casework, it is whether every sentence in the answer points to the exact section it rests on.
The order also makes the evaluation understandable to the people who own the workflow. A head of department does not need to know what faithfulness is to say that an answer without a source reference is unusable. That sentence is a success criterion, and it can be measured.
“The most important measurement is rarely a generic score. It depends on the task.”
Three to five measurements are usually enough: one or two specific to the task, and two or three that follow the architecture. More measurements give you a dashboard nobody acts on.
The eval set must contain what goes wrong
An evaluation dataset that only contains the questions the system already answers correctly measures nothing. It also has to hold hard cases, edge cases and known failure modes: ambiguous questions, conflicting information and questions with no answer in the knowledge base.
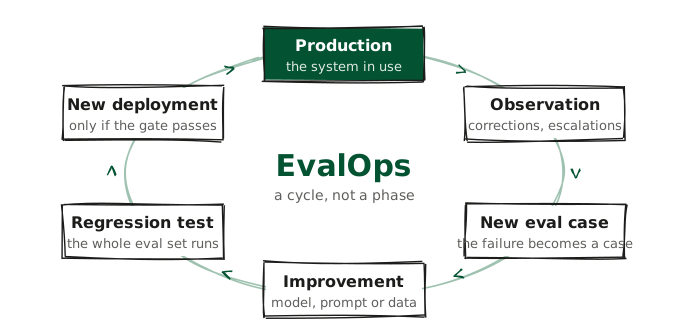
Every failure that shows up in production is added to the set. That way it is not just fixed once. It becomes a regression test that catches it if it comes back.
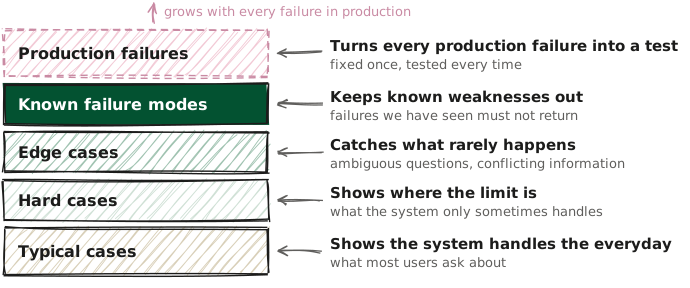
The dataset is versioned together with the system. A score belongs to a specific version of the set, and two scores measured on different versions cannot be compared directly.
Without component measurements you do not know what to fix
When a RAG solution gives a wrong answer, the fault can lie in three places. The search never found the relevant document. It found it, but irrelevant passages were ranked higher. Or the model got the right context and still wrote something it did not support.
The end result is the same wrong answer in all three cases. The fix is different: different chunking or more search results in the first, a reranker in the second, the prompt and a source-reference requirement in the third. Only component-level measurements can tell them apart: context recall, context precision and faithfulness.
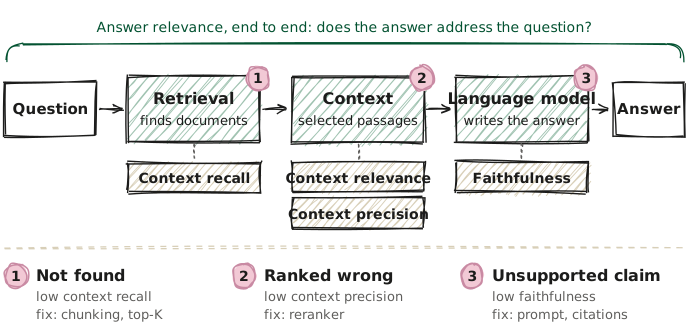
End-to-end evaluation tells you what goes wrong. The components tell you where. The same holds for agents: tool correctness shows whether the agent used the right tools, and task completion shows whether the task was actually solved. Correct steps are not the same as a solved task.
An AI judge must be calibrated before it may judge
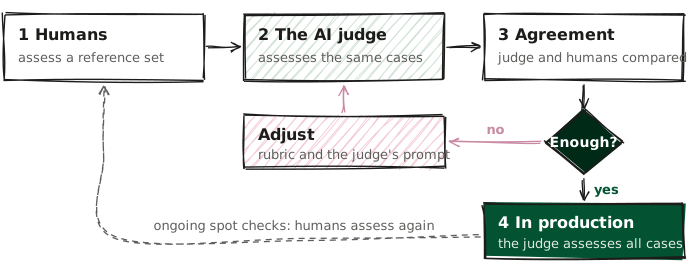
Most quality questions in generative AI cannot be settled with pass/fail. There is no single correct summary. So we let another language model assess the answers against a clearly defined rubric. That makes it possible to evaluate far more answers at every change than a human could get through.
But the judge is itself a language model. Its assessments can shift with the wording of the criteria and with the order in which the answers are presented. So humans first assess a reference set, and we measure whether the judge agrees with them. Only when agreement is high enough does the judge run on all cases, and the measurement is repeated every time the judge's model or prompt changes.
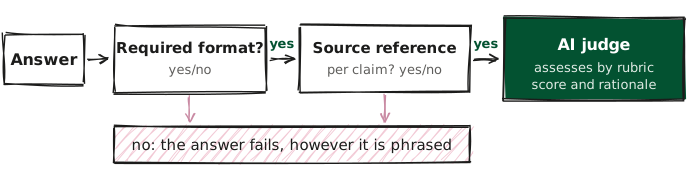
Hard requirements are settled before the judge even sees the answer, with deterministic yes/no checks: does the answer have the required format? Does every claim have a source reference? An answer without a source reference fails, however well it is otherwise phrased.
Evals are a quality gate, also after go-live
The real value comes when the eval set runs automatically every time someone changes the model, prompt, retrieval, chunking or agent logic. If a critical measurement falls below the agreed level, the deployment is stopped, just as a build is stopped by failing tests. The threshold is set per measurement and per use case, according to what a failure costs in the specific workflow.
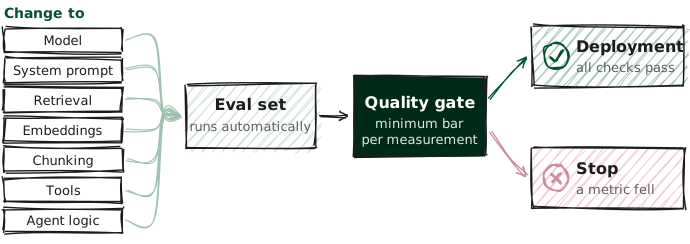
That changes the conversation in the team.
The new model seems better at first glance.
The new configuration improves task completion, holds the minimum requirement for faithfulness and reduces latency.
Evaluation does not stop at go-live. Users find new uses, the data changes, and external models can change behaviour without anyone touching the system. Corrections, overrides and escalations to humans are the most honest quality signals we have. The most important of them become new cases in the eval set.
The most important measurement lies in the workflow
A higher faithfulness score is not the same as more productive employees. An agent can solve more tasks correctly and at the same time create so much checking work that the overall process becomes slower. Technical measurements are leading indicators. They have to be held up against what happens in the workflow, continuously, and if the score rises without the workflow getting better, we are measuring the wrong thing.
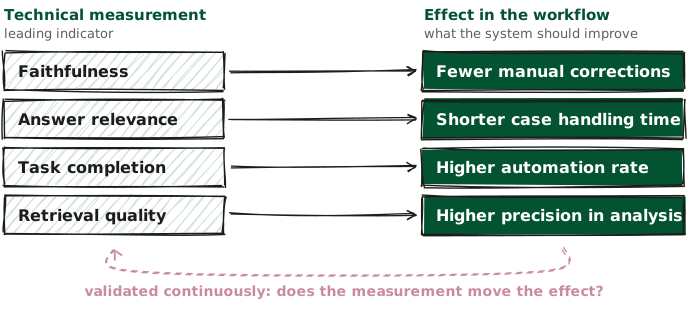
In a solution we have built for the unemployment insurance sector, the technical measurement is that every answer points to its statutory basis. The effect in the workflow is that the number of manual legal lookups per case is 0–1. In a delivery to the insurance and pensions industry, we extract insurance data with roughly 98% precision for Open Finance and FiDA. The last 2% are not hidden away, because a system that cannot say where it is uncertain cannot be used for anything with legal effect.
- 0–1
- manual legal lookups per case in a solution for the unemployment insurance sector. The technical measurement is the source reference to the statutory basis.
- approx. 98%
- precision on insurance data in a delivery to the insurance and pensions industry, for use in Open Finance and FiDA.
For systems classified as high-risk under the AI Act, this is not just good practice. The Act requires testing against predefined metrics and thresholds, automatic logging and systematic monitoring after deployment. An organisation that already measures quality systematically has the documentation ready when the supervisory authority asks.
The simplest place to start is one test: can you run the same evaluation again tomorrow and get a number you can compare with today's? If not, you have an assessment, not a measurement.